Python

Exporting Indigo device list to CSV
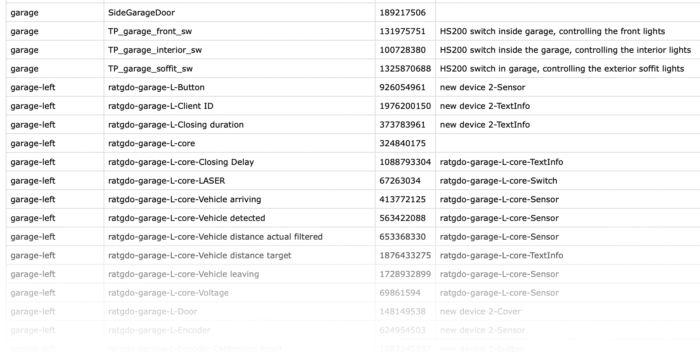
Indigo device list

Sometimes I find myself needing to code something for Indigo, the macOS home automation application, and I would like to have my list of devices available. Rather than connect to my Indigo server to look up each device’s name or ID, it would be convenient to have a list at hand whenever I need it.

You can run the following script in the Indigo scripting shell, opened via Plugins > Open Scripting Shell in Indigo. The script exports device names, IDs, and descriptions to a CSV file, sorted alphabetically by folder and then by device name. Device descriptions appear in the Notes column. Devices outside a folder appear under (no folder).

Friday, September 4, 2026

The Indigo SQL Logger plugin can save device states to a local SQLite database that is stored in Indigo’s current version support directory. But where is that directory and how can our scripts access it agnostic of the current version of Indigo?

It turns out that the server exposes its log directory path:

indigo.server.getLogsFolderPath()

Then to get the path to the device state database:

import os

db_path = os.path.join(indigo.server.getLogsFolderPath(), 
    "indigo_history.sqlite")

And as an example:

Updated: ARINC 424 parser & explainer

Yesterday I posted about a small utility that parses and explains ARINC 424 records. I have updated it.

For each field, the tool now cites the specific tables in the ARINC 424 specification that describe that field. The field-content explanations are also more detailed, so you can spend less time flipping between the parsed output and the printed standard. Here is an example for an Airport SID/STAR/Approach primary record:

This is still a work in progress. Not all record types are supported yet; I am filling those in as I need them.

A small utility to parse and explain ARINC 424 records

N.B. An enhanced version is now available, with specification table references and more detailed field explanations. 2026-08-03.

The ARINC 424 specification is the universally accepted standard for encoding aeronautical navigation data. Databases that follow it store that data in fixed-length, 132-character records. I created a utility that parses a single ARINC 424 record and prints the fields along with column numbers and plain-language explanations. The Python arinc424 module does the heavy lifting; I provide a wrapper around it, plus the logic that maps fields to the column numbers used in the official specification.

Scripting Shelly relay devices in Indigo

This is a proof-of-concept for scripting Shelly relay devices in an Indigo Python action.

I’ve used the Indigo macOS home automation software for many years. It’s a deep, extensible and reliable piece of software. Among the extensible features of the application is its suite of community-supported plugins. There is a plugin for Shelly devices, but it supports only earlier devices and not the current units. As I understand it, the author does not intend to update the plugin. In this post, I’ll show a method for controlling these devices without plugins. The shortcoming here is that the Shelly device doesn’t have a corresponding Indigo device, and everything is handled through action groups and variables.

Thursday, April 17, 2025

vim: Jump to specific character on a line

In Vim, to jump to a specific character on a line, you can use the following commands:

  • f{char} - Jump to the next occurrence of {char} on the current line
  • F{char} - Jump to the previous occurrence of {char} on the current line
  • t{char} - Jump until (one position before) the next occurrence of {char}
  • T{char} - Jump until (one position after) the previous occurrence of {char}

For your specific example of “go to first #”:

An API (sort of) for adding links to ArchiveBox

I use ArchiveBox extensively to save web content that might change or disappear. While a REST API is apparently coming eventually, it doesn’t appear to have been merged into the main fork. So I cobbled together a little application to archive links via a POST request. It takes advantage of the archivebox command line interface. If you are impatient, you can skip to the full source code. Otherwise I’ll describe my setup to provide some context.

Scraping Forvo pronunciations

Most language learners are familiar with Forvo, a site that allows users to download and contribute pronunciations for words and phrases. For my Russian studies, I make daily use of the site. In fact, to facilitate my Anki card-making workflow, I am a paid user of the Forvo API. But that’s where the trouble started.

When the Forvo API works, it works OK, often extremely slow. But lately, it has been down more than up. In an effort to patch my workflow and continue to download Russian word pronunciations, I wrote this little scraper. I’d prefer to use the API, but experience has shown now that the API is slow and unreliable. I’ll keep paying for the API access, because I support what the company does. And as often as not when a company offers a free service, it’s likely to be involved in surveillance capitalism. So I’d rather companies offer a reliable product at a reasonable price.

A tool for scraping definitions of Russian words from Wikitionary

In my perpetual attempt to make my language learning process using Anki more efficient, I’ve written a tool to extract English-language definitions from Russian words from Wiktionary. I wrote about the idea previously in Scraping Russian word definitions from Wikitionary: utility for Anki but it relied on the WiktionaryParser module which is good but misses some important edge cases. So I rolled up my sleeves and crafted my own solution. As with WiktionaryParser the heavy-lifting is done by the Beautiful Soup parser. Much of the logic of this tool is around detecting the edge cases that I mentioned. For example, the underlying HTML format changes when we’re dealing with a word that has multiple etymologies versus those with a single etymology. Whenever you’re doing web scraping you have to account for those sorts of variations.